湾芯展将于2026年10月14日至16日在深圳会展中心(福田)举行。展会同期,“算力及大模型产业创新发展论坛”将于10月15日下午在会展中心6楼郁金香厅举行。
本次论坛汇聚算力与大模型产业链企业,聚焦国产算力技术创新与大模型应用落地,围绕异构计算、互连与存储协同、国产生态适配等核心议题,分享芯片与系统创新、智算基础设施建设及模型部署优化的一线经验,呈现国产算力在半导体行业与智能终端中的应用实践,共探高效算力供给与产业生态协同的发展路径。

产业生态合作伙伴

赞助合作

WESEMiBAY 2026
议程抢先一览

WESEMiBAY 2026
嘉宾阵容揭晓


演讲简介/亮点
在方兴未艾的AI Agent浪潮中,计算需求激增,算力基础设施正在经历“通算CPU为中心”到“通算CPU-智算XPU异构协同”的范式转移,也是未来基础设施优化、释放AI潜力至千行百业的演进主线。本报告系统梳理CPU-XPU在向量/矩阵指令加速以及异构融合上的演进规律,并概要介绍希奥端公司基于自身芯片产品,在Agent异构计算方向所做的一些深入思考与探索。
In the burgeoning wave of AI Agents, computational demands are surging, and computing infrastructure is undergoing a paradigm shift from "general-purpose CPU-centric computing" to "general-purpose CPU & intelligent XPU heterogeneous collaboration," which is also the main evolutionary thread for future infrastructure optimization and unlocking AI's potential across all industries. This report systematically reviews the evolution of CPU-XPU in vector/matrix instruction acceleration and heterogeneous integration, and provides a brief introduction to some in-depth reflections and explorations by Theo End Computing in the direction of Agent heterogeneous computing, based on its own chip products.


演讲简介/亮点
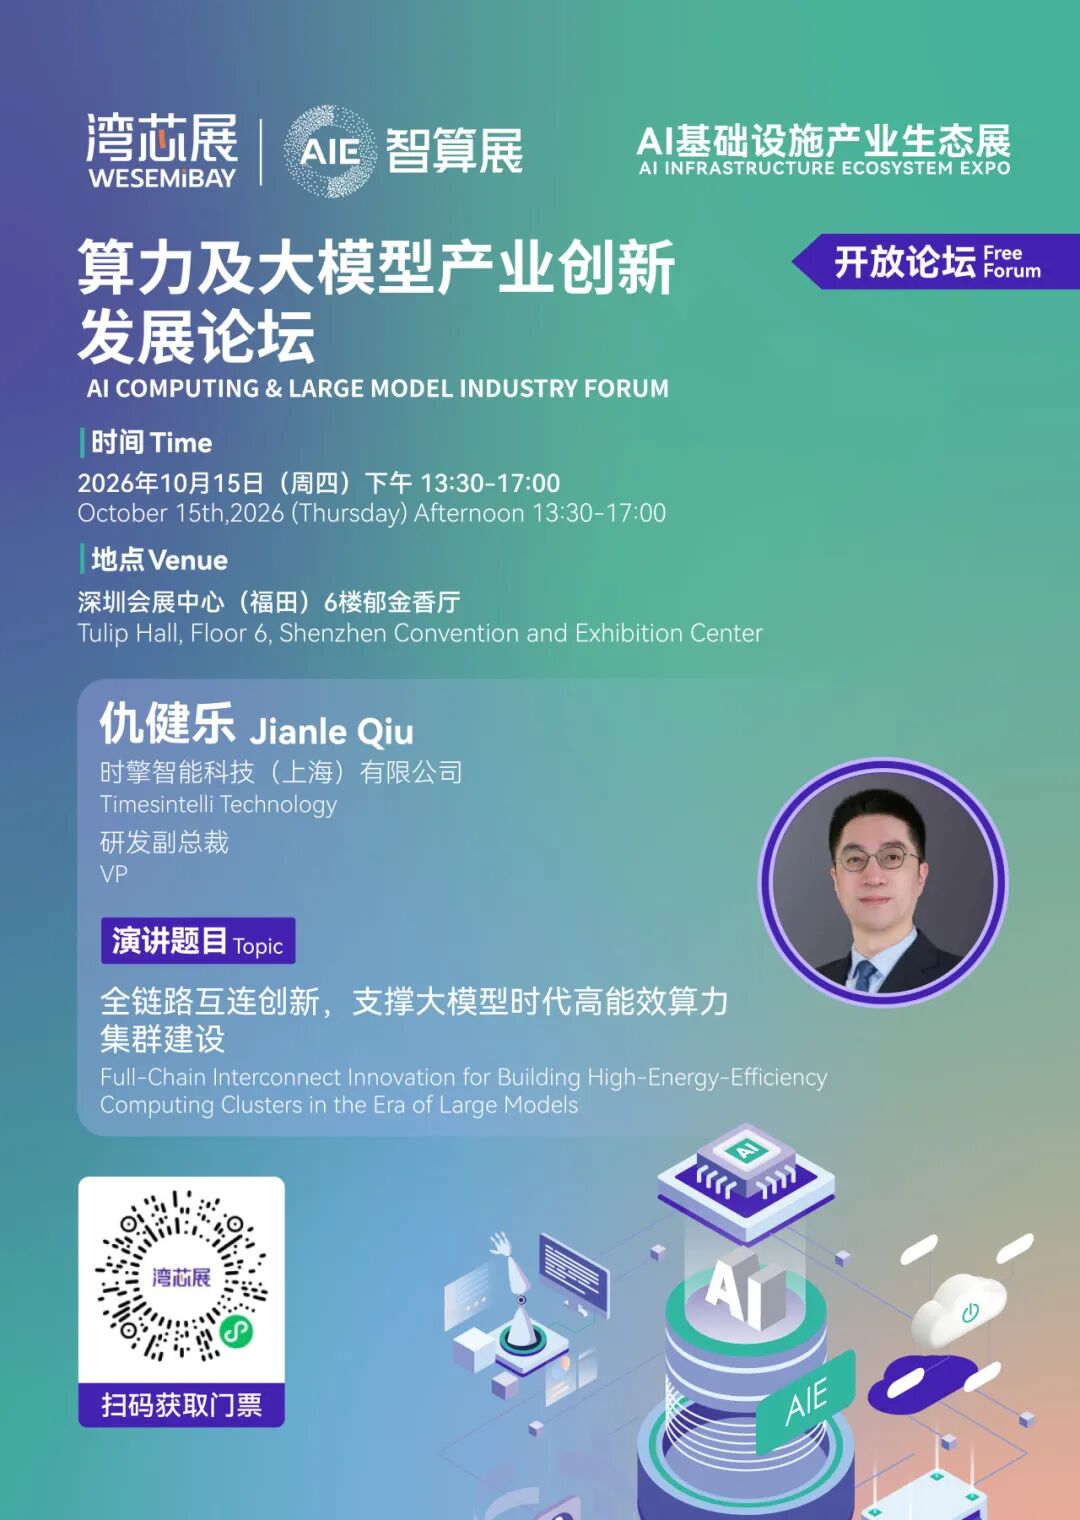
大模型时代,高能效算力集群的建设不仅取决于核心计算芯片,更取决于全链路互连的创新能力。作为终端连接网络的核心物理接口,网卡芯片长期由少数国际厂商主导,其技术集成高性能 CPU、复杂协议栈与高速模拟电路,设计门槛极高。在信息技术应用创新与供应链安全备受关注的背景下,实现互连芯片的自主供应,已成为夯实数字基础设施自主底座的关键环节。
时擎科技PT153S 作为一款全国产化 USB 千兆网卡芯片,功能丰富、性能强劲、功耗低,可广泛应用于 USB 千兆网卡、扩展坞、PC、嵌入式工业主板等电子产品。其全国产化设计切实保障供应链安全,集成 RISC-V CPU 与完整解决方案,显著降低行业客户导入门槛、缩短开发周期。未来产业化将双线推进:市场层面依托性价比与定制化服务优势,在信创、工业控制等自主性要求高的领域实现快速替代与渗透;生态层面通过驱动兼容认证与开放开发支持,逐步构建国产网卡芯片软硬件应用生态。
本次演讲将分享 PT153S 在全链路互连创新中的产业化实践,探讨以自主可控的互连芯片支撑大模型时代高能效算力集群建设,助力夯实我国数字基础设施的自主底座。
In the era of large models, building high-energy-efficiency computing clusters depends not only on core compute chips, but equally on innovation across the full-chain interconnect. As the core physical interface connecting terminals to the network, network interface controllers (NICs) have long been dominated by a handful of international vendors. Integrating high-performance CPUs, complex protocol stacks, and high-speed analog circuits, these chips present exceptionally high design barriers. Amid growing concerns over IT application innovation and supply chain security, achieving self-sufficient supply of interconnect chips has become a critical enabler for strengthening the autonomous foundation of digital infrastructure.
PT153S of Timesintelli Technology, a fully domestic USB Gigabit Ethernet controller, delivers rich functionality, strong performance, and low power consumption. It can be widely deployed in USB Gigabit adapters, docking stations, PCs, embedded industrial motherboards, and more. Its fully domestic design ensures supply chain security, while the integrated RISC-V CPU and complete solution significantly lower customers' adoption barriers and shorten development cycles. Looking ahead, industrialization will advance along two tracks: on the market side, leveraging cost-effectiveness and customization to achieve rapid replacement and penetration in Xinchuang (IT application innovation) and industrial control sectors that demand high autonomy; on the ecosystem side, building a domestic software–hardware application ecosystem for NICs through driver compatibility certification and open development support.
This session will share PT153S's industrialization practices in full-chain interconnect innovation, and discuss how autonomous interconnect chips can underpin the construction of high-energy-efficiency computing clusters in the large-model era.


演讲简介/亮点
基于忆阻器的存算一体芯片技术——从技术验证到产业化实践
随着大模型规模快速增长,“存储墙”已成为制约AI算力与能效提升的关键瓶颈。忆阻器存算一体技术通过原位计算减少数据搬运,为突破这一瓶颈提供了重要路径,但其产业化仍面临良率、可靠性、计算精度及软硬件协同等挑战。
忆元科技是清华大学集成电路学院科技成果转化企业,也是全球较早实现忆阻器存算一体芯片工程化落地的企业之一。公司具备覆盖器件、阵列、芯片架构、系统软件及应用的全链条技术能力,已完成多个工艺节点的技术验证,并推出面向数据中心的忆阻器存算一体向量检索加速卡。
本报告将介绍忆元科技从器件创新到系统应用的产业化实践,重点分享其在“百亿千维”向量检索及搜索推荐、大模型知识库等场景中的应用进展,并探讨该技术向大模型推理芯片和训推一体通用芯片演进的发展趋势。
Memristor-Based Compute-in-Memory Chip Technology: From Innovation to Products
As LLM-based AI application grow rapidly, the “memory wall” has become a major bottleneck for computing performance and energy efficiency. Memristor-based compute-in-memory reduces data movement by performing computation directly in memory. It offers a promising way to overcome this bottleneck, but commercialization still faces challenges in yield, reliability, computing accuracy, and hardware-software integration.
Elemem Technology is a technology spin-off from Tsinghua University’s School of Integrated Circuits and one of the first companies worldwide to commercialize memristor-based compute-in-memory chips. The company has end-to-end expertise in devices, arrays, chip architecture, system software, and applications. It has validated its technology across multiple process nodes and launched a memristor-based vector search accelerator card for data centers.
This presentation will introduce Elemem’s path from device innovation to commercial systems. It will highlight progress in large-scale vector search, search and recommendation, and knowledge bases for large AI models. It will also explore the evolution of this technology toward large-model inference chips and general-purpose chips for both training and inference.
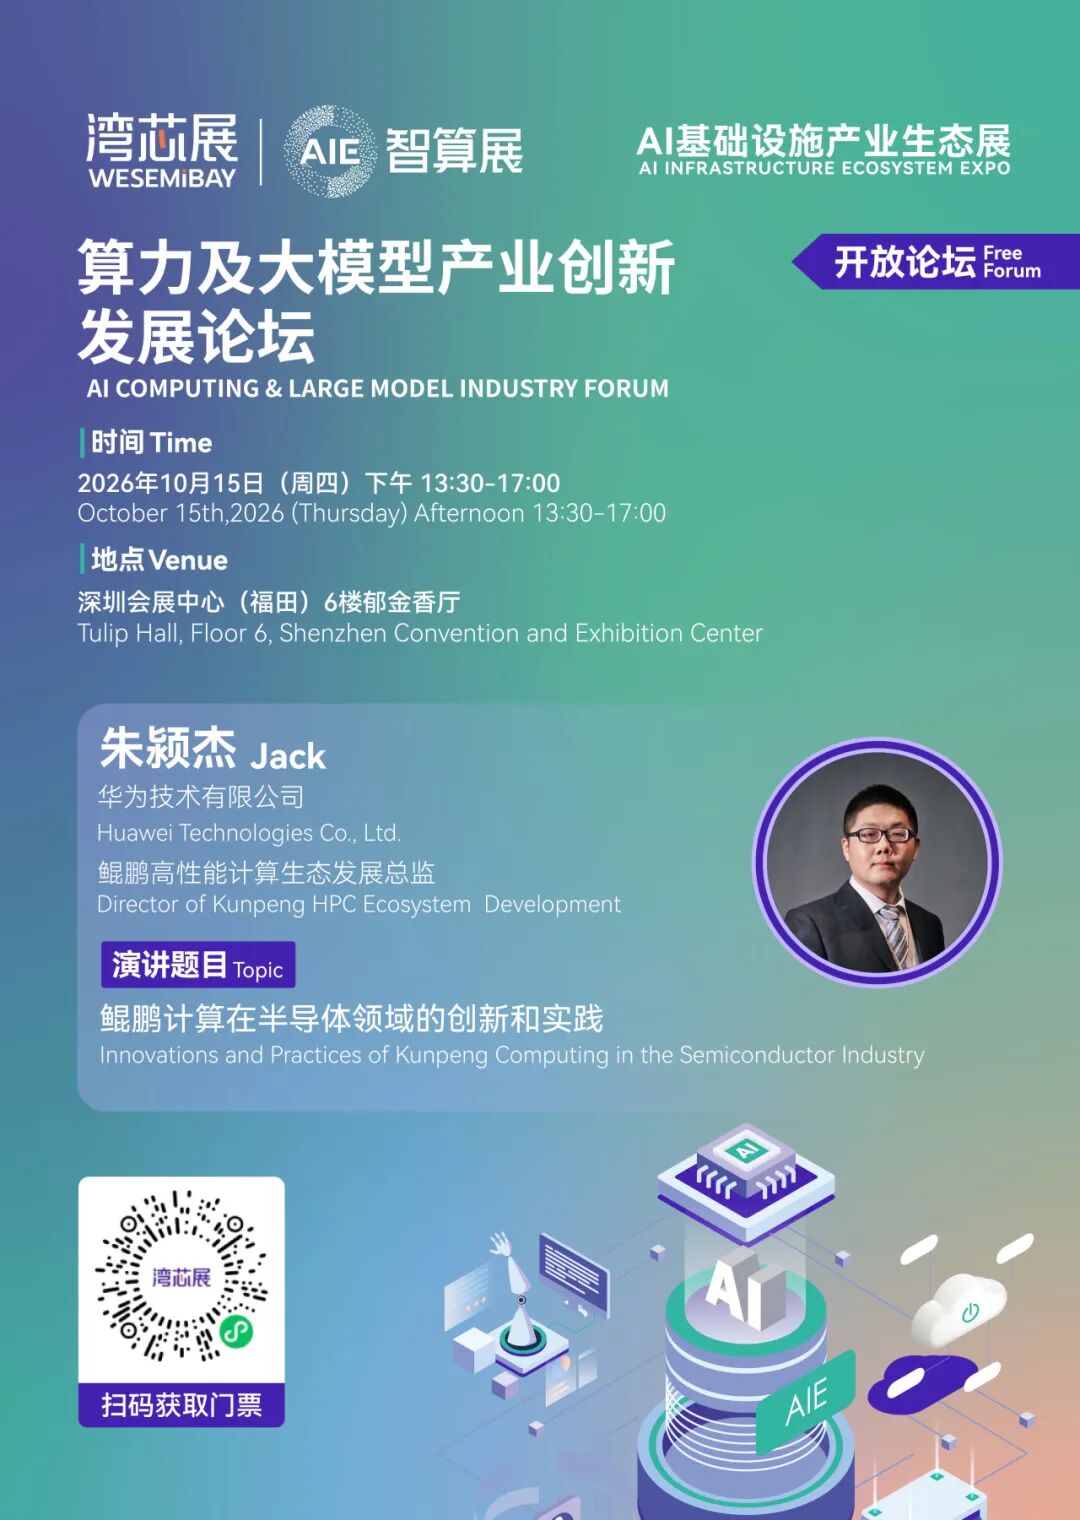


演讲简介/亮点
围绕半导体行业发展关键瓶颈,分享鲲鹏新一代处理器关键能力,基础软件和计算体系结构创新实践,鲲鹏处理器国产半导体生态适配最近进展,分享鲲鹏在半导体行业落地实践,共谋自主算力引领半导体行业创新发展新方向。
Focusing on key bottlenecks in the development of the semiconductor industry, this presentation shares the core capabilities of the new-generation Kunpeng processors, innovative practices in foundational software and computing architecture, recent progress in adapting Kunpeng processors to the domestic semiconductor ecosystem, as well as Kunpeng’s deployment practices in the semiconductor sector. We aim to jointly explore new directions for the innovative development of the semiconductor industry empowered by self-reliant computing power.


演讲简介/亮点
探讨如何突破数据供给、存储带宽与算力利用率之间的瓶颈。内容将从训练与推理场景出发,解析高性能存储、数据智能调度、缓存优化及软硬件协同等关键技术.
Explore how storage-compute synergy can overcome bottlenecks in data delivery, storage bandwidth, and compute utilization. Focusing on both model training and inference, the presentation will examine key technologies—including high-performance storage, intelligent data scheduling, cache optimization, and hardware-software co-design—to maximize infrastructure efficiency and unlock the full computing potential of large language models.
WESEMiBAY 2026
10月相聚深圳湾芯展
诚邀算力与大模型产业链的专业观众莅临现场,与嘉宾共同交流国产算力创新、大模型部署与行业应用实践。

扫码加入论坛交流群
*更多嘉宾及议程信息将陆续公布,最终安排以现场公布为准。欢迎扫码加入论坛交流群,及时获取议程更新与现场动态。

点击“阅读原文”,快速进入湾芯展观众报名通道!